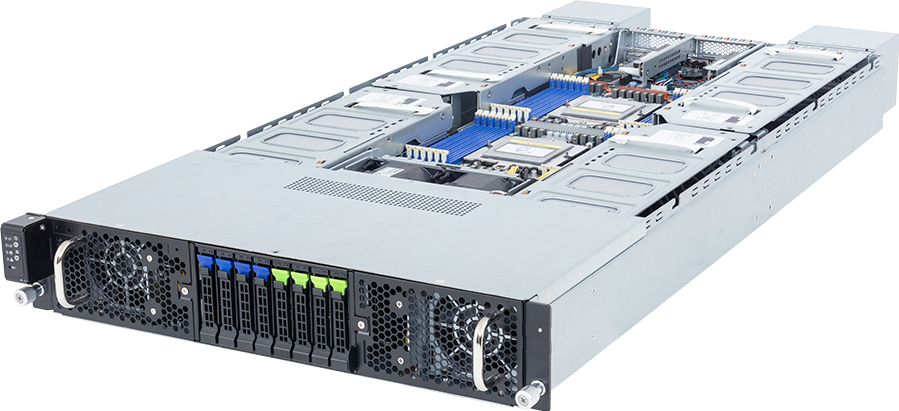
The GIGABYTE G294-Z42-AAP2 is a 2U dual-socket AMD EPYC server with eight full-height, full-length PCIe Gen5 x16 GPU slots behind PCIe switches. That headline needs an important qualification. GIGABYTE's published examples are four NVIDIA H200 NVL cards, four NVIDIA RTX PRO 6000 Blackwell Server Edition cards, or eight AMD Radeon AI PRO R9700S cards. The chassis should not be quoted as an arbitrary eight-card NVIDIA system without checking the current GPU support list.
This makes the G294-Z42-AAP2 a flexible but highly specific PCIe platform. It suits inference replicas, visual computing, simulation and accelerator jobs that can use independent GPUs or the limited peer links available to a qualified card. It is not an HGX replacement when one training job needs all eight GPUs inside a single NVSwitch scale-up domain.
Configure the GIGABYTE G294-Z42-AAP2 after fixing the GPU model, workload, power feed and network plan. The barebone specification alone does not define a safe configuration.
G294-Z42-AAP2 specifications that affect the purchase
| Component | Published specification | Buying implication | | --- | --- | --- | | Chassis | 2U, 448 x 87.5 x 962 mm including rear fans | Check rack depth, rear clearance and cable bend radius | | Processor | Two AMD EPYC 9005 or 9004 processors, SP5 | Both sockets are needed for the complete lane and memory design | | CPU power | Up to 240 W cTDP, or up to 300 W at 30°C ambient | CPU choice changes the thermal and power margin available to GPUs | | Memory | 24 DDR5 RDIMM slots, 12 channels per processor | Balanced 12-DIMM-per-CPU population gives the cleanest bandwidth layout | | GPU slots | Eight FHFL PCIe Gen5 x16 slots through PEX89048 switches | Slot count does not override the qualified GPU list | | Other expansion | Two low-profile PCIe Gen5 x16 slots from CPU 0 | Reserve them deliberately for cluster, storage or security adapters | | Front storage | Four 2.5-inch Gen5 NVMe/SATA/SAS-4 bays plus four SATA/SAS-4 bays | Only four front bays have a published NVMe path; SAS needs an add-in card | | Onboard network | Two 10GbE ports plus a dedicated management port | Most cluster or high-throughput storage designs need an additional NIC | | Power supplies | Two 3,000 W 80 PLUS Titanium units | Available output depends on input voltage; confirm full-load redundancy | | Cooling | Eight 80 x 80 x 80 mm fans | The qualified GPU, inlet temperature and fan policy must be treated together |
GIGABYTE states that a single-CPU installation can disable some PCIe or memory functions. For a dense GPU build, plan this as a dual-processor server unless the supplier has validated a specific one-socket configuration.
The GPU support list is the central decision
The eight GPU slots do not mean every dual-slot accelerator can be installed eight times. The current product page names three layouts with very different memory, power and software characteristics.
Four NVIDIA H200 NVL GPUs
H200 NVL is a PCIe Hopper accelerator with 141 GB of HBM3e and a configurable power ceiling of up to 600 W. Four cards provide 564 GB of aggregate GPU memory, but that memory is not one transparent pool. GIGABYTE validates the cards as two two-GPU sets, each joined by a two-way NVLink bridge.
That topology can suit models or jobs that fit within one or two GPUs and benefit from a fast peer link inside each pair. It does not reproduce an eight-GPU HGX H200 baseboard. HGX connects eight SXM GPUs through NVSwitch, while this server presents two bridged pairs of PCIe H200 NVL cards. Software placement and communication patterns therefore matter.
GIGABYTE specifies a 25°C ambient condition for the four-card H200 NVL layout. Treat that as a design constraint, not a footnote. The data hall must supply the required inlet temperature and airflow under sustained load.
Four NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs
The RTX PRO 6000 Blackwell Server Edition provides 96 GB of ECC GDDR7 memory and a configurable 400 W to 600 W power range. Four cards provide 384 GB of aggregate VRAM. This route is attractive when one server must support AI inference, fine-tuning, rendering, simulation, media processing or virtual-workstation workloads without moving to a fixed HGX baseboard.
These are PCIe accelerators. Workloads that use one card per worker, replica or user can make good use of that flexibility. A tightly coupled job that exchanges data across all four cards should be tested before purchase because PCIe communication is not the same as an HGX NVLink and NVSwitch fabric.
The server's specification warns that GPU display outputs are unavailable because of mechanical limitations. Buyers needing direct physical displays should not treat this as a rack-mounted four-user workstation. Remote graphics, vGPU and compute use need their own software and licensing checks.
GIGABYTE also specifies a 25°C ambient condition for this four-card layout. The GPU power setting, CPU selection and inlet temperature should be written into the approved configuration.
Eight AMD Radeon AI PRO R9700S GPUs
The Radeon AI PRO R9700S is a 300 W, 32 GB GDDR6 card based on AMD RDNA 4. Eight cards provide 256 GB of aggregate VRAM. AMD publishes Linux ECC support and ROCm compatibility for the product.
This layout gives the server its highest published card count, but it should be selected for software that has been validated on the exact ROCm release and GPU target. Eight independent cards can suit parallel inference, development, media or batch workloads. Total VRAM across the chassis is not the same as memory available to one process, and PCIe card count does not create an HGX-style shared scale-up fabric.
GIGABYTE says the system is validated with a uniform GPU model. Do not mix GPU families or board variants unless a current supplier-approved configuration explicitly allows it.
PCIe switching changes how to read the slot count
The eight GPU slots are connected through Broadcom PEX89048 PCIe switches rather than each slot being wired as a simple direct CPU endpoint. PCIe switching makes the dense 2U layout possible and can support peer traffic, but the practical path between a GPU, CPU memory and an add-in network card depends on the board topology.
The two low-profile x16 slots are connected from CPU 0. If one of those slots carries a high-speed storage or cluster adapter, confirm which GPUs have the shortest data path to it and whether the application can preserve PCIe locality. This is especially important for GPUDirect RDMA, distributed training and high-rate model loading.
Ask the supplier for a topology capture from the completed system, then map processes and NICs accordingly. A list of eight x16 slots does not by itself prove that every concurrent transfer can sustain x16 bandwidth or avoid crossing sockets.
CPU and memory configuration
The platform accepts AMD EPYC 9005 and 9004 processors. Each socket has 12 memory channels and the server provides 24 DIMM slots in total. GIGABYTE lists up to 6,400 MT/s memory with EPYC 9005 and up to 4,800 MT/s with EPYC 9004, subject to the chosen CPU and DIMMs.
For GPU workloads, CPU selection should follow the host-side work:
- Data loading, tokenisation, decompression and simulation can justify more cores.
- Latency-sensitive orchestration may value clock speed over the largest core count.
- Virtualisation and multiple independent GPU workers need enough cores per tenant or service.
- Storage and network processing consume CPU and memory bandwidth alongside the application.
Populate memory symmetrically across both sockets. A large capacity built with too few DIMMs can leave channels unused and reduce host-memory bandwidth. Also reserve RAM for the operating system, containers, page cache, data workers and management agents instead of assigning the full installed capacity to the primary application.
The thermal note matters here. The server supports CPU cTDP up to 240 W generally and up to 300 W at 30°C ambient. A high-power CPU pair is not a free upgrade in a 2U, multi-GPU chassis. The final combination must remain inside the vendor's thermal table.
Storage is eight front bays, not eight NVMe bays
The front storage layout has two groups:
- Four 2.5-inch hot-swap bays support PCIe Gen5 NVMe, SATA or SAS-4.
- Four additional 2.5-inch hot-swap bays support SATA or SAS-4.
SAS requires an add-in controller. The second group does not have a published NVMe path. This distinction should be reflected in the configurator so a buyer cannot select eight NVMe drives merely because eight front bays are visible.
The four hybrid bays share physical positions between supported drive types. If two are filled with NVMe drives, those same two positions cannot also hold SATA or SAS drives. Storage quantities must respect the common bay limit.
For an AI node, the NVMe group can hold operating-system mirrors, model cache, active datasets or checkpoint scratch. Large clusters normally keep authoritative datasets and checkpoints on shared storage. Local capacity should be sized around the workflow and recovery plan, not used as a substitute for data protection.
Networking and cluster fit
The server includes two 10GbE data ports through a Broadcom BCM57416 controller and a separate management interface. That is useful for deployment, user traffic and basic storage access, but it is not a substitute for a scale-out AI fabric.
The two low-profile PCIe Gen5 x16 slots can host faster network adapters, subject to the supported-device list and airflow. Choose the link speed from measured traffic rather than the GPU count. Independent inference workers may need modest east-west bandwidth, while distributed training, remote storage or frequent checkpointing can require 100, 200 or 400 Gb/s links and a matched switch design.
Keep management available when the data fabric is busy. For a cluster, calculate switch ports, optics, cables, oversubscription and failure paths for the complete node count. The GPU cluster configurator can provide a starting topology, but the final network must follow the selected GPU and application.
Power, voltage and rack planning
Each power supply is rated up to 3,000 W, but that output is not available from every feed:
- At 100 to 127 V AC, the published maximum is 1,000 W per supply.
- At 200 to 220 V AC, the published maximum is 2,600 W per supply.
- At 220 to 240 V AC, the published maximum is 3,000 W per supply.
The server requires C19 power cords. A dense GPU configuration belongs on a verified 200 to 240 V data-centre circuit, with the actual current, connector, PDU and redundancy policy checked before delivery.
Do not use two 3,000 W labels as proof of 6 kW usable redundant power. If the design must survive one failed supply, the complete configured load must fit the vendor's supported redundancy envelope on the remaining feed. Four 600 W GPUs already account for up to 2.4 kW before CPUs, memory, drives, NICs, PCIe switches and fans. Obtain the supplier's power budget for the exact bill of materials.
The chassis is 962 mm deep when its rear fans are included. Leave room for rails, power connectors, network cables and service access. Confirm the rack's usable depth, static load and rear-door clearance rather than relying on its nominal external dimension.
Workload fit
The G294-Z42-AAP2 makes sense for:
- PCIe GPU inference where replicas or workers can be scheduled per card or per H200 NVL pair.
- Rendering, media, design and virtual-workstation services using qualified RTX PRO cards.
- Simulation and HPC codes that have been tested on the selected PCIe accelerator.
- ROCm-based development or parallel AI jobs using the qualified R9700S layout.
- Teams that need a dense 2U node but do not require eight GPUs in one NVSwitch domain.
It is a poor fit when:
- A single training job needs uniform high-bandwidth communication across eight GPUs.
- The buyer assumes eight physical slots permit eight H200 NVL or eight RTX PRO 6000 cards.
- The facility cannot provide the required input voltage, inlet temperature or rack depth.
- The software stack has not been validated on the chosen NVIDIA or AMD card.
- Four NVMe bays are insufficient for the planned local dataset and no shared-storage design exists.
For tightly coupled eight-GPU training, compare the HGX server range. For lower-density or mixed PCIe deployments, review the wider PCIe GPU server catalogue.
Configuration checklist
Before approving a quote, record:
1. The exact GPU part number, quantity, power setting and current GIGABYTE qualification. 2. Whether the workload uses independent cards, two-card NVLink pairs or multi-card PCIe communication. 3. Both CPU models and their cTDP settings. 4. A symmetric 24-slot memory population plan, including speed and capacity. 5. The split between four hybrid NVMe/SATA/SAS bays and four SATA/SAS-only bays. 6. Any SAS or RAID controller and the low-profile slot it consumes. 7. The cluster or storage NIC, its slot, firmware, transceivers and switch ports. 8. Input voltage, C19 cabling, PDU capacity and one-feed failure behaviour. 9. Rack depth, inlet temperature, airflow and rear service clearance. 10. Operating system, drivers, CUDA or ROCm release and application validation.
The supplier should test the completed system with the intended GPU count and power profile. A barebone POST test is not a workload acceptance test.
FAQ
Can the G294-Z42-AAP2 take eight NVIDIA H200 NVL GPUs?
The current GIGABYTE product page validates four H200 NVL cards, installed as two pairs with two-way NVLink bridges. It does not list an eight-card H200 NVL configuration. Use the current support list when ordering.
Is this an HGX server?
No. It is a PCIe GPU server. The qualified H200 NVL layout uses two-card NVLink bridges, not an eight-GPU HGX NVSwitch baseboard. Buyers needing one tightly connected eight-GPU scale-up domain should compare HGX systems.
How many NVMe drives does it support?
GIGABYTE publishes four front Gen5 bays that can accept NVMe, SATA or SAS drives. The other four front bays are SATA or SAS. SAS support requires an add-in card.
Can the server run from a 120 V circuit?
The power supplies accept 100 to 127 V input, but GIGABYTE limits output to 1,000 W per supply at that voltage. That is not enough for the dense GPU configurations discussed here. Confirm a supported 200 to 240 V feed and full-load redundancy with the supplier.
Which GPU layout should I choose?
Use H200 NVL when its HBM capacity, Hopper software path and two-card NVLink pairing fit the application. Use RTX PRO 6000 for a blend of AI, graphics, simulation and virtual-workstation work. Consider R9700S where the exact workload is validated on ROCm and independent 32 GB cards fit the scheduling model.
Can GPUMachines host the system?
Hosted deployment can be assessed with the configuration. The review should cover rack depth, per-feed power, cooling, external connectivity, remote management and the network path to datasets before a hosting quote is approved.
Verdict
The GIGABYTE G294-Z42-AAP2 packs a useful amount of PCIe accelerator capacity into 2U, but its value comes from the qualified configuration rather than the slot count. Four H200 NVL cards, four RTX PRO 6000 cards and eight R9700S cards describe three different systems with different memory, power, software and communication behaviour.
Choose it when independent or lightly coupled GPU work suits a dense PCIe platform and the facility can support the voltage, temperature and depth requirements. Choose HGX when the workload needs one high-bandwidth eight-GPU scale-up domain.
Open the G294-Z42-AAP2 configurator and submit the intended workload for GPU, CPU, memory, storage, network and power review.
Technical sources
- GIGABYTE G294-Z42-AAP2 product page
- GIGABYTE G294-Z42-AAP2 system manual
- NVIDIA H200 product specifications
- NVIDIA RTX PRO 6000 Blackwell Server Edition specifications
- AMD Radeon AI PRO R9700S specifications
Specifications and qualified components can change. Confirm the current GIGABYTE support list and supplier-approved bill of materials before ordering.