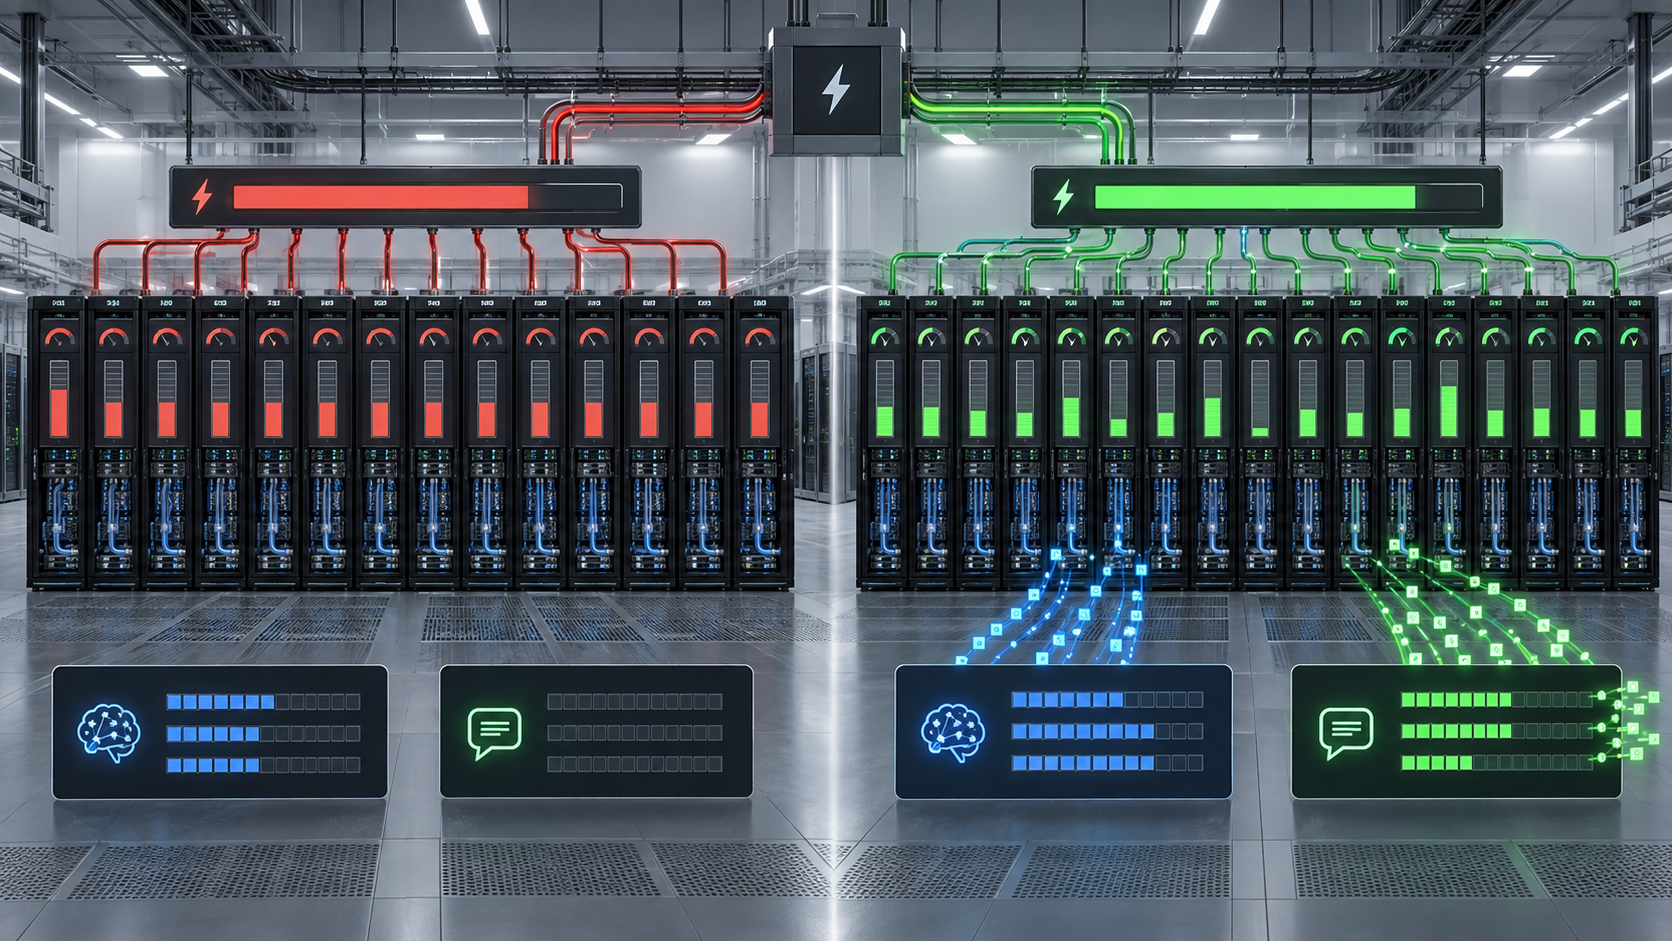
Power is now a hard capacity limit for many GPU deployments. A data centre may have room for another rack and budget for more GPUs, yet still be unable to obtain more utility capacity on the required timetable. In that situation, the useful question is not simply how many accelerators fit in the building. It is how much completed work the site can produce inside its available megawatts.
NVIDIA says its DSX MaxLPS software can improve that result by moving power between GPU nodes as workload demand changes. In a proof of concept with Lambda, NVIDIA reported that 19 HGX B200 nodes running at 85% of their maximum power delivered roughly 5 million tokens per second, compared with about 4 million tokens per second from 16 nodes at full power within the same power budget. That is a reported 24% increase in cluster token throughput and a 23% improvement in performance per watt.
Those figures are useful, but they are not a universal sizing rule. They came from a vendor-led test on a specific platform and workload. Buyers should treat them as a reason to test dynamic allocation against their own service-level targets, not as a guaranteed saving.
What dynamic GPU power allocation actually changes
Conventional cluster planning often assigns a fixed power ceiling to each server or rack. The design is easy to explain and leaves clear electrical margins, but it assumes every node needs its maximum allowance at the same time. Real AI workloads rarely behave that neatly. Prefill, decode, data loading, checkpointing and inter-node communication can place different demands on the system from one moment to the next.
Dynamic allocation uses telemetry and policy to redistribute a shared power budget. A busy node can receive more power while another node, whose workload is not turning extra watts into useful output, is capped lower. The aim is not to make an individual GPU faster at any cost. It is to complete more useful work across the cluster without exceeding the facility limit.
This matters because GPU performance does not usually scale linearly with power. The last portion of a device's power envelope can produce a smaller performance gain than the first portion. Operating more nodes below their maximum power can therefore outperform fewer nodes running flat out, provided the workload can use the additional parallel capacity.
The Lambda example illustrates that trade. Sixteen nodes at full power were compared with 19 nodes at 85%. The latter group stayed within the same stated power budget while producing more aggregate tokens. It does not mean every cluster should add 19% more nodes or cap every GPU at 85%. The best point depends on model architecture, batch size, latency target, networking, cooling and the efficiency curve of the accelerator.
Tokens per megawatt is useful, but incomplete
Tokens per second tells an inference operator how much language-model output the cluster can produce. Dividing that output by power makes it easier to compare operating points under a site constraint. It can also expose a poor design that buys expensive accelerators without giving them enough useful work.
The metric still needs boundaries. A credible result should state:
- whether power was measured at the GPU, server, rack distribution unit or utility feed;
- whether cooling, networking and storage power were included;
- the model, precision, context length, batch policy and input/output token mix;
- whether the test held first-token latency and inter-token latency constant;
- how long the run lasted and whether throttling or queue growth appeared;
- what happened when a node, job or power-management service failed.
A result measured only at the accelerator can help tune GPUs, but it cannot establish facility capacity. Conversely, a utility-level measurement includes losses and overhead that the GPU software cannot control. Buyers should ask for both where possible.
For training, tokens per megawatt may not be the right primary measure. Time to train, samples per second at a defined quality target, or useful accelerator hours per megawatt may be more meaningful. The principle is the same: choose a workload outcome, hold quality and service targets constant, then compare total energy and elapsed time.
Where the commercial value comes from
Dynamic power control is most valuable when electrical capacity is the binding constraint. If a site has spare utility, cooling and switchgear capacity, the operator may get a better return by running fewer nodes at their most efficient operating point and delaying extra hardware purchases.
The case becomes stronger when:
- a utility upgrade would take months or years;
- the cluster mixes interactive inference, batch inference and training;
- workloads have different priority and latency requirements;
- demand varies enough for power to be shifted between jobs;
- the operator can schedule flexible work around electricity price or grid events;
- the facility has instrumentation accurate enough to enforce a shared limit.
NVIDIA also describes DSX Flex, which can react to grid requests or electricity pricing by reducing low-priority workloads while protecting higher-priority services. In a separate demonstration with Emerald AI and Silicon Valley Power, NVIDIA reported a reduction from 4 MW to 3 MW in under a minute. That is an interesting demand-response result, but it should not be confused with uninterrupted application performance. Buyers need to define which workloads may slow down, for how long, and how the scheduler restores them.
Fixed allocation versus dynamic allocation
| Decision area | Fixed per-node limits | Dynamic shared limit | | --- | --- | --- | | Capacity planning | Simple and conservative | Can recover stranded capacity | | Operational complexity | Lower | Requires telemetry, policy and control integration | | Workload fit | Predictable steady loads | Mixed or time-varying loads | | Failure behaviour | Local limits remain clear | Control-plane and fallback behaviour must be tested | | SLA protection | Capacity is reserved physically | Priorities must be expressed and enforced in software | | Evidence required | Nameplate and stress test | Workload, power-boundary and failover tests |
Neither approach is automatically superior. A research cluster with irregular jobs may benefit from policy-based sharing. A tightly regulated production service may prefer fixed reservations for its critical partition and dynamic allocation for lower-priority capacity.
What to test before buying around the claim
Ask the supplier to run an acceptance test using the models and serving stack you expect to operate. A useful test has at least three operating points: the proposed dynamic policy, a fixed-power baseline with the same installed hardware, and a lower node-count baseline within the same facility power ceiling.
Record throughput, latency percentiles, queue depth, error rate and power at the same time. Repeat the test at more than one load level. A policy that looks efficient at saturation may add little value during normal demand, while an aggressive cap may damage tail latency before average throughput visibly falls.
Then inject failure. Disconnect telemetry from one node, restart the controller, exceed the rack limit briefly and stop a workload while power is being reallocated. The cluster should fail to a known conservative state rather than let a software fault become an electrical event.
The commercial proposal should also state what is included. Dynamic power software cannot repair an undersized cooling loop, insufficient busway, poor rack distribution or a network bottleneck. Use the GPU cluster configurator to frame the compute requirement, then validate rack power, cooling and fabric as one design. Buyers comparing rack-scale platforms can review the available HGX server range.
Questions for the supplier
1. What exact workload produced the quoted efficiency result? 2. Where was power measured, and which facility overheads were excluded? 3. Which latency and quality targets were held constant? 4. How quickly does the policy move power, and how does it avoid oscillation? 5. What happens if telemetry is stale or the controller is unavailable? 6. Can critical services reserve a minimum power level? 7. Is the proposed gain based on measured customer hardware or a projection? 8. Which software licences, agents and management services are required?
NVIDIA projects that suitable Vera Rubin NVL72 deployments may support up to 40% more GPU capacity through these techniques. That is a forward-looking vendor projection, not a result buyers should place directly into a business case. The right number is the gain reproduced on the proposed platform under the buyer's workload and facility constraints.
Should you deploy more GPUs under the same cap?
Do it when power is genuinely scarce, the workload can spread across more nodes, and the measured gain survives your latency and failure tests. Do not do it simply because an efficiency percentage appears in a vendor presentation. Additional nodes still carry capital cost, network ports, cooling load, software licences and maintenance obligations.
For teams that need the capacity but do not want to own the electrical and cooling integration, Buy & Host can separate hardware ownership from facility operation. The same diligence still applies: define the power boundary, workload target and service commitment before comparing an owned installation with hosted capacity.
The practical lesson is straightforward. A megawatt is not a workload outcome. Dynamic allocation can turn a fixed electrical envelope into more completed work, but only when the cluster, scheduler and facility are measured together.